NVIDIA / Pascal
Tesla P100
No rental offers yet
Published offers will appear here when a provider lists this GPU.
Prices are dated listings, not live availability. Compare minimum GPU counts and commitments. Storage, networking and taxes may add charges; CPU/RAM inclusion depends on the provider and is shown beside each serverless rate.
Tesla P100 is a professional compute or workstation GPU based on NVIDIA’s Pascal architecture. This reference profile records 16 GB of HBM2 memory and 3584 CUDA cores. Its listed memory bandwidth is 732 GB/s.
Reference configuration: PCIe 16 GB. PCIe 12 GB and SXM2 16 GB versions also exist. The provider label does not identify the edition; do not apply the PCIe power or interconnect values to SXM2. This hardware profile is independent of current rental availability.
Its usable workload size depends on the entire memory budget. Model weights, KV cache, runtime buffers and temporary tensors all consume VRAM. Quantization can reduce weight storage, but it does not guarantee that a model fits or that an inference engine supports the card.
This generation has no Tensor Cores or hardware ray-tracing cores. Check an older, compatible CUDA toolchain and framework build before using it for machine learning; current inference packages may require a newer GPU architecture.
Rental availability is tracked separately from this hardware profile. If no provider offer is listed, XPU has no verified current rental price for this item. Hardware specifications remain useful for comparing equipment, but they are not a live offer or a promise of availability.
CHOOSING THIS GPU
Is it right for your workload?
Reference configuration: PCIe 16 GB. PCIe 12 GB and SXM2 16 GB versions also exist. The provider label does not identify the edition; do not apply the PCIe power or interconnect values to SXM2. This hardware profile is independent of current rental availability.
Best suited to
- Graphics and CUDA workloads that fit the listed VRAM
- Small quantized-model experiments after checking engine support
- Development workloads where runtime compatibility is verified
Strengths
- 16 GB reference memory capacity
- Pascal architecture with an explicit CUDA capability
- Hardware details separated from rental-provider availability
Things to consider
- Installed board edition and usable VRAM need confirmation
- GPU memory also holds KV cache, activations and runtime buffers
- No measured throughput is inferred from theoretical specifications
- No Tensor Cores or RT Cores; modern inference engines may reject this architecture
HARDWARE DETAILS
Inside the GPU
Reference configuration: PCIe 16 GB. PCIe 12 GB and SXM2 16 GB versions also exist. The provider label does not identify the edition; do not apply the PCIe power or interconnect values to SXM2. This hardware profile is independent of current rental availability.
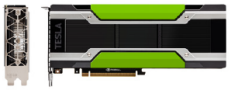
Image: Manufacturer reference image; exact provider board and cooling may differ.
- Manufacturer
- NVIDIA
- Architecture
- Pascal
- VRAM (GB)
- 16
- Memory type
- HBM2
- Form factor
- PCIe add-in card
- Memory bandwidth (GB/s)
- 732
- Maximum board power (W)
- 250
- Introduction year
- 2016
- CUDA cores
- 3584
- Tensor cores
- Not present
- Ray tracing cores
- Not present
- CUDA capability
- 6.0
- Memory ECC
- Supported; driver configuration determines enablement
- Host interface
- PCIe 3.0 x16
- GPU interconnect
- NVLink on SXM2 only; reference PCIe card has no NVLink
- Hardware partitioning (MIG)
- Not supported
- Cooling
- Passive; server airflow required
Hardware capabilities are not a guarantee of access in a cloud instance. Check the exact edition, GPU allocation and server topology in the rental offer.
MODEL MEMORY
Plan your model size
Estimate weights as parameters multiplied by bytes per parameter, then add runtime buffers and KV cache. For example, 7B weights occupy about 14 GB in FP16, 7 GB in INT8 or 3.5 GB in 4-bit before overhead. This is arithmetic guidance, not a verified fit or speed benchmark for this GPU.
| Example model class | Weight format | Raw weights ≈ | Minimum GPUs for weights only |
|---|---|---|---|
| Llama 3.1 8B ↗ | 4-bit | 4 GB | 1Runtime needs more memory |
| Llama 3.1 8B ↗ | FP16 | 16 GB | 1Runtime needs more memory |
| Qwen2.5 14B ↗ | 4-bit | 7 GB | 1Runtime needs more memory |
| Qwen2.5 32B ↗ | 4-bit | 16 GB | 1Runtime needs more memory |
| Llama 3.1 70B ↗ | 4-bit | 35 GB | 3Runtime needs more memory |
| Llama 3.1 70B ↗ | 8-bit | 70 GB | 5Runtime needs more memory |
| Llama 3.1 70B ↗ | FP16 | 140 GB | 9Runtime needs more memory |
Arithmetic lower bound: rounded parameter count × bits per weight ÷ 8, in decimal GB. Excludes quantization metadata, KV cache, activations, CUDA workspaces and training states. Actual model sizes differ from their rounded names. No context length, batch size or concurrency is guaranteed. GPU counts assume supported model sharding and can be higher in practice. Quantized checkpoints and compatible kernels are required for 4-bit/8-bit execution.
SOFTWARE & PERFORMANCE
Before you deploy
Software compatibility
For Maxwell and Pascal, use a compatible CUDA 12.x-era toolchain and framework build that includes this compute capability. CUDA 13 removed offline compilation support for these architectures. Do not assume a current CUDA container or vLLM build supports this GPU.
Measured benchmarks
A reproducible, comparable application benchmark has not yet been recorded for this edition. Peak TFLOPS above are not measured tokens per second or image-generation speed.
Compare tests using the same model, precision, GPU count, engine version, input/output length and batch or concurrency. A provider’s server configuration can change the result.
COMPARE YOUR OPTIONS
Alternatives to consider
BUDGET YOUR RUN
GPU cost estimator
An eligible hourly price is not recorded. Check the rental terms below for quotes or reserved commitments.