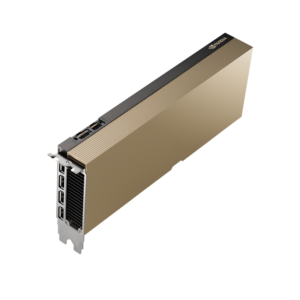
NVIDIA / Ada Lovelace
L40
| Provider / plan | Price / GPU-hour | Rental type | Terms & configuration | Last checked | Provider pricing link |
|---|---|---|---|---|---|
| Vast.aiBest on-demand | $0.5081Updated 2026-11-22 · 15:43 UTCLowest flexible rate | On-demandNo reservation | 1 GPU minimumNew York, USView detailsObserved marketplace offer, not a provider-wide list rate. Total hourly quote for one GPU with the API default disk allocation; bandwidth and additional storage can cost extra. One cheapest verified available on-demand offer per GPU is selected; availability can change.
|
2026-11-22Auto-collected | View pricing ↗ |
| Runpodbest-on-demand | $0.69Updated 2026-11-22 · 15:43 UTC | On-demandNo reservation | 1 GPU minimumSee providerView detailsCommunity Cloud: lowest public on-demand GPU-hour list rate among enabled clouds. Not a capacity guarantee; storage/networking extra.
|
2026-11-22Auto-collected | View pricing ↗ |
Prices are dated listings, not live availability. Compare minimum GPU counts and commitments. Storage, networking and taxes may add charges; CPU/RAM inclusion depends on the provider and is shown beside each serverless rate.
L40 combines a hardware profile with dated rental offers on xpu live. L40 is an Ada data-center GPU with 48 GB of ECC memory for rendering, visualization and AI inference. Its graphics and media capabilities suit mixed visual-computing workloads. It should not be treated as an L40S with the same performance.
L40 specifications and configuration
The catalog records Ada Lovelace architecture, 48 GB of VRAM, GDDR6 memory, PCIe form factor, 864 GB/s memory bandwidth, 300 W maximum board power. These values describe the documented hardware edition. They do not describe the CPU, system RAM or storage of every cloud machine. Open the Specifications tab for the full field-by-field comparison.
L40, not L40S. NVIDIA publishes different Tensor compute and power specifications for these two 48 GB cards. Consult the manufacturer specification source when checking the exact edition.
Choosing L40 for your workload
L40 is worth comparing for Remote visualization and complex 3D scenes; AI inference alongside graphics workloads; GPU rendering and video processing. Its documented strengths include 48 GB GDDR6 with ECC; Dedicated ray tracing and video engines; 300 W reference power envelope. Match those features to the application you intend to run rather than treating a model name as a performance guarantee.
Before deployment, consider No NVLink or MIG; Lower published Tensor throughput than L40S; Passive cooling requires a supported server. Compare 8B/14B FP16 and larger quantized models using the weight-only estimates below. A 70B 4-bit model has about 35 GB of raw weights before quantization metadata and runtime memory; nominal capacity alone does not establish a fit.
L40 rental prices and total cost
The rental table separates provider, plan, hourly rate and rental type. Compare on-demand capacity with reserved, spot and serverless terms where those options are listed. The lowest displayed number is not necessarily the lowest total bill for your workload.
Check the last-checked date, minimum GPU count, included CPU and RAM, disk charges and network fees. Confirm availability directly with the provider before paying. Marketplace quotes describe individual machines and can disappear; they are not a permanent provider-wide price.
Compare alternatives before renting
Use the GPU explorer to compare memory and architecture, or browse GPU cloud providers. For L40, test the same model, precision, batch size and context length on the proposed instance. Record latency, throughput and total cost so your comparison reflects the actual task.
CHOOSING THIS GPU
Is it right for your workload?
L40, not L40S. NVIDIA publishes different Tensor compute and power specifications for these two 48 GB cards.
Best suited to
- Remote visualization and complex 3D scenes
- AI inference alongside graphics workloads
- GPU rendering and video processing
Strengths
- 48 GB GDDR6 with ECC
- Dedicated ray tracing and video engines
- 300 W reference power envelope
Things to consider
- No NVLink or MIG
- Lower published Tensor throughput than L40S
- Passive cooling requires a supported server
HARDWARE DETAILS
Inside the GPU
L40, not L40S. NVIDIA publishes different Tensor compute and power specifications for these two 48 GB cards.
Image: Reference hardware; rental provider cooling configuration may differ.
- Manufacturer
- NVIDIA
- Architecture
- Ada Lovelace
- VRAM (GB)
- 48
- Memory type
- GDDR6
- Form factor
- PCIe
- Memory bandwidth (GB/s)
- 864
- Maximum board power (W)
- 300
- Introduction year
- 2022
- CUDA cores
- 18176
- Tensor cores
- 568 / 4th generation
- Ray tracing cores
- 142 / 3rd generation
- CUDA capability
- 8.9
- Memory ECC
- Supported
- Host interface
- PCIe Gen4 x16
- GPU interconnect
- Not supported
- Hardware partitioning (MIG)
- Not supported
- Cooling
- Passive; server airflow required
Hardware capabilities are not a guarantee of access in a cloud instance. Check the exact edition, GPU allocation and server topology in the rental offer.
MODEL MEMORY
Plan your model size
Compare 8B/14B FP16 and larger quantized models using the weight-only estimates below. A 70B 4-bit model has about 35 GB of raw weights before quantization metadata and runtime memory; nominal capacity alone does not establish a fit.
| Example model class | Weight format | Raw weights ≈ | Minimum GPUs for weights only |
|---|---|---|---|
| Llama 3.1 8B ↗ | 4-bit | 4 GB | 1Runtime needs more memory |
| Llama 3.1 8B ↗ | FP16 | 16 GB | 1Runtime needs more memory |
| Qwen2.5 14B ↗ | 4-bit | 7 GB | 1Runtime needs more memory |
| Qwen2.5 32B ↗ | 4-bit | 16 GB | 1Runtime needs more memory |
| Llama 3.1 70B ↗ | 4-bit | 35 GB | 1Runtime needs more memory |
| Llama 3.1 70B ↗ | 8-bit | 70 GB | 2Runtime needs more memory |
| Llama 3.1 70B ↗ | FP16 | 140 GB | 3Runtime needs more memory |
Arithmetic lower bound: rounded parameter count × bits per weight ÷ 8, in decimal GB. Excludes quantization metadata, KV cache, activations, CUDA workspaces and training states. Actual model sizes differ from their rounded names. No context length, batch size or concurrency is guaranteed. GPU counts assume supported model sharding and can be higher in practice. Quantized checkpoints and compatible kernels are required for 4-bit/8-bit execution.
SOFTWARE & PERFORMANCE
Before you deploy
Software compatibility
Use an NVIDIA CUDA-enabled framework/container compatible with this GPU and the host driver. Check PyTorch build and inference-engine kernel requirements before deployment. vLLM documents NVIDIA compute capability 7.5+ as a baseline; support for each model and quantization method still needs checking.
Measured benchmarks
A reproducible, comparable application benchmark has not yet been recorded for this edition. Peak TFLOPS above are not measured tokens per second or image-generation speed.
Compare tests using the same model, precision, GPU count, engine version, input/output length and batch or concurrency. A provider’s server configuration can change the result.
COMPARE YOUR OPTIONS
Alternatives to consider
BUDGET YOUR RUN
GPU cost estimator
GPU compute only: hourly rate × billable hours × GPU count. CPU, RAM, storage, egress, taxes, billing increments and minimum terms may add charges. Serverless hours mean active GPU task time; spot capacity can be interrupted. Reserved commitments and quote-only offers are excluded from this simple hourly estimator.